To report AI search share of voice to clients or executives, show one number (your mentions divided by all mentions of you and your tracked competitors), plot it as a trend over weeks, split it by engine and competitor, state the prompt set behind it, and finish with what you will do next. Do not send a single-day snapshot, because AI answers vary between runs.
This guide is about the reporting itself: what to put on the page, how to word it, and how to handle the awkward questions. For choosing software, see AI share of voice tools.
What is AI search share of voice, in one sentence a client will understand?
AI search share of voice is the portion of brand mentions in AI answers that belong to you, compared with the competitors you chose to track. In Citeflare, it is your mentions divided by all mentions of you and your tracked competitors, across the prompts and engines in the selected window.
Say it that plainly at the top of the report. Executives rarely need the mechanics; they need to know that 100% is the whole tracked field and that your slice is the part you hold.
It is worth distinguishing it from its sibling, the visibility score: the share of completed prompt runs where your brand is mentioned at all. Visibility answers "are we named?" Share of voice answers "are we named more than the others?" Report both, but lead with the one that matches the audience's question.
How do I structure the report so executives actually read it?
Open with a one-screen summary, then put evidence behind it. A workable order:
- Headline: share of voice this period, the change versus last period, and one sentence explaining the cause.
- Trend line: at least six to eight weeks, so a dip reads as noise or signal rather than a surprise.
- Breakdown: by engine, by competitor, and by prompt group.
- Evidence: two or three real answers that show how you were named, or missed.
- Actions: what you will do, who owns it, and when the next report lands.
Keep the appendix for the full prompt list and methodology. Clients who want it will ask; those who don't will not be buried.
What should I define before the first report goes out?
Agree the measurement contract in writing first. Otherwise every later movement invites an argument about the method rather than the result.
- Competitor set: which brands count. Adding a competitor mid-quarter lowers your share without anything having changed, so log the date of any change.
- Prompt set: the buyer questions you track, grouped by intent (category discovery, comparison, problem-led). Note that in Citeflare a prompt is one question, and tracking it in several countries counts each country separately.
- Engines: which assistants are included. Citeflare tracks ChatGPT, Claude, Gemini, Perplexity, Grok, DeepSeek, Mistral, Llama, Google AI Overviews and Google AI Mode.
- Window: weekly or monthly, and a fixed rule for comparing periods.
- Country and language: results can differ by market, so name the one being reported.
This is also where you explain how the data is gathered: each engine is asked your prompts through its API and the answer is stored. That is a sample of answers, not a census of everything every user sees.
How do I explain that AI answers vary from run to run?
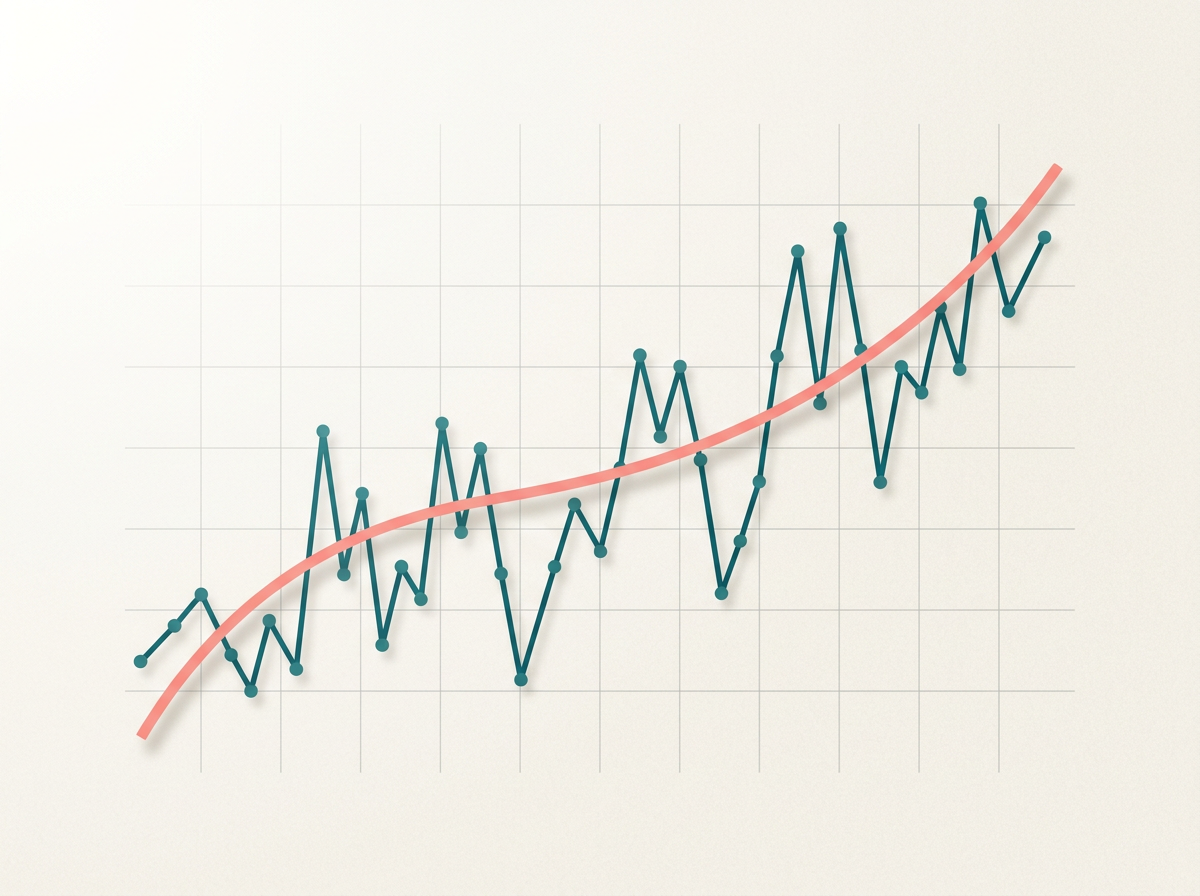
Tell stakeholders up front that the figure is a trend line, not a guarantee, and show it as one. Because answers vary between runs, a single day's score can mislead. A rolling view across many prompts and many days smooths that out.
A practical wording for a report footer: "Scores come from daily scans of a fixed prompt set. We read direction over several weeks and treat single-day moves as noise." For the deeper reasoning, point curious readers to what variance means for tracking accuracy.
Also beware of percentage changes on tiny bases. Going from one mention to three is a 200 percent rise that tells a reader almost nothing. Report the counts and the number of prompt runs alongside the percentage.
Which breakdowns matter most to clients?
The three that change decisions are engine, competitor and prompt group. Each answers a different follow-up question.
| Breakdown | Question it answers | What to show |
|---|---|---|
| By engine | Where are we strong or invisible? | Share of voice per assistant, side by side |
| By competitor | Who is taking the share we lack? | Brands by engines grid, with period change |
| By prompt group | Which buying stage are we losing? | Share on discovery vs comparison questions |
| By country | Is the picture the same in each market? | Share per market for the same prompts |
| By citation source | Which sites shape the answers? | Top cited domains, Reddit threads, YouTube videos |
The competitor view is usually the one executives remember, so make it clear and consistent. In Citeflare this is the brands-by-engines view in competitor share of voice.
How do I show why the numbers moved?
Explain movement with sources and content, not guesses. Citation analysis shows which domains, Reddit threads and YouTube videos appear in answers, and your share of those citations. If a competitor gained share, check whether they gained a new citation source you lack. See how to find which sites and Reddit threads AI cites for the method.
For a drop, a short diagnosis helps: which engine, which prompt group, which competitor, and whether your own site changed. Crawler logs can add a clue: if GPTBot or PerplexityBot stopped reaching key pages or hit errors, say so. Background in AI crawlers explained.
Label each explanation as confirmed, likely or unknown. Executives trust a report that admits uncertainty far more than one that claims certainty and gets caught.
Should I connect AI share of voice to traffic and revenue?
Only as far as your data supports it. Share of voice is a visibility measure, and many AI answers produce no click. Present it as an upstream indicator next to traffic and pipeline, not as a cause of them. If referral traffic from AI assistants is visible in your analytics, show it separately and say what share of total it represents. If you cannot attribute revenue, write that plainly rather than implying it.
How do clients differ from executives in what they want?
Clients want proof of work and direction; executives want a decision.
- Agency clients: include what was published or fixed, which gaps remain, and how their share compares with named rivals. A white-label-style summary per brand keeps multi-client reporting manageable; Citeflare projects each hold their own brand, competitors, country and language, which helps agencies keep reports separate. See AI search visibility for agencies.
- Executives and boards: one slide, one trend, one risk, one ask. Frame it as a channel: is it growing, are we ahead, and what does it need?
What should the report end with?
End with decisions, owners and a date. A list such as "publish comparison content for the three prompts where we are absent," "fix crawler errors on the pricing path," and "review again on the first Monday of next month" turns a status document into a plan. Citeflare's Tasks turn scans into ranked next steps with critical gaps first, which gives you ready material for this section, and its analyst agent can draft a weekly recap from your own data. Both are optional; a spreadsheet works if your process is consistent.
For wider context on what to measure beyond share of voice, read how to measure your visibility in AI answers.
A simple report template
- Share of voice, change versus last period, one-line cause
- Visibility score and trend (6-8 weeks)
- Engine and competitor breakdown
- Two real answers: one win, one gap
- Top cited sources and changes
- Actions with owners and dates
- Method note: prompt set, engines, country, competitor list, change log
FAQ
How often should I report AI share of voice?
Monthly suits most clients and executives, with a weekly internal check. Weekly reports to stakeholders tend to overreact to normal variation.
How many prompts do I need for a trustworthy figure?
There is no universal number. Use enough prompts to cover each buying stage and market, keep the set stable, and report the count of runs behind each figure.
What is a good share of voice?
It depends on how many competitors you track and your category. Compare against your own earlier periods and against the named rivals rather than a universal benchmark.
Can I report one engine only?
Yes, but say so. Engines differ, so a strong result on one can hide weakness on another. Showing the engine split avoids that.
Do Google rankings predict AI share of voice?
Not reliably. Treat AI answers as a separate channel and report them separately from organic rankings.
Can Citeflare produce the data for these reports?
Yes. It records daily prompt runs, share of voice against tracked competitors, citations and crawler activity, and starts with a 7-day free trial. See pricing for plan limits.